Architecture
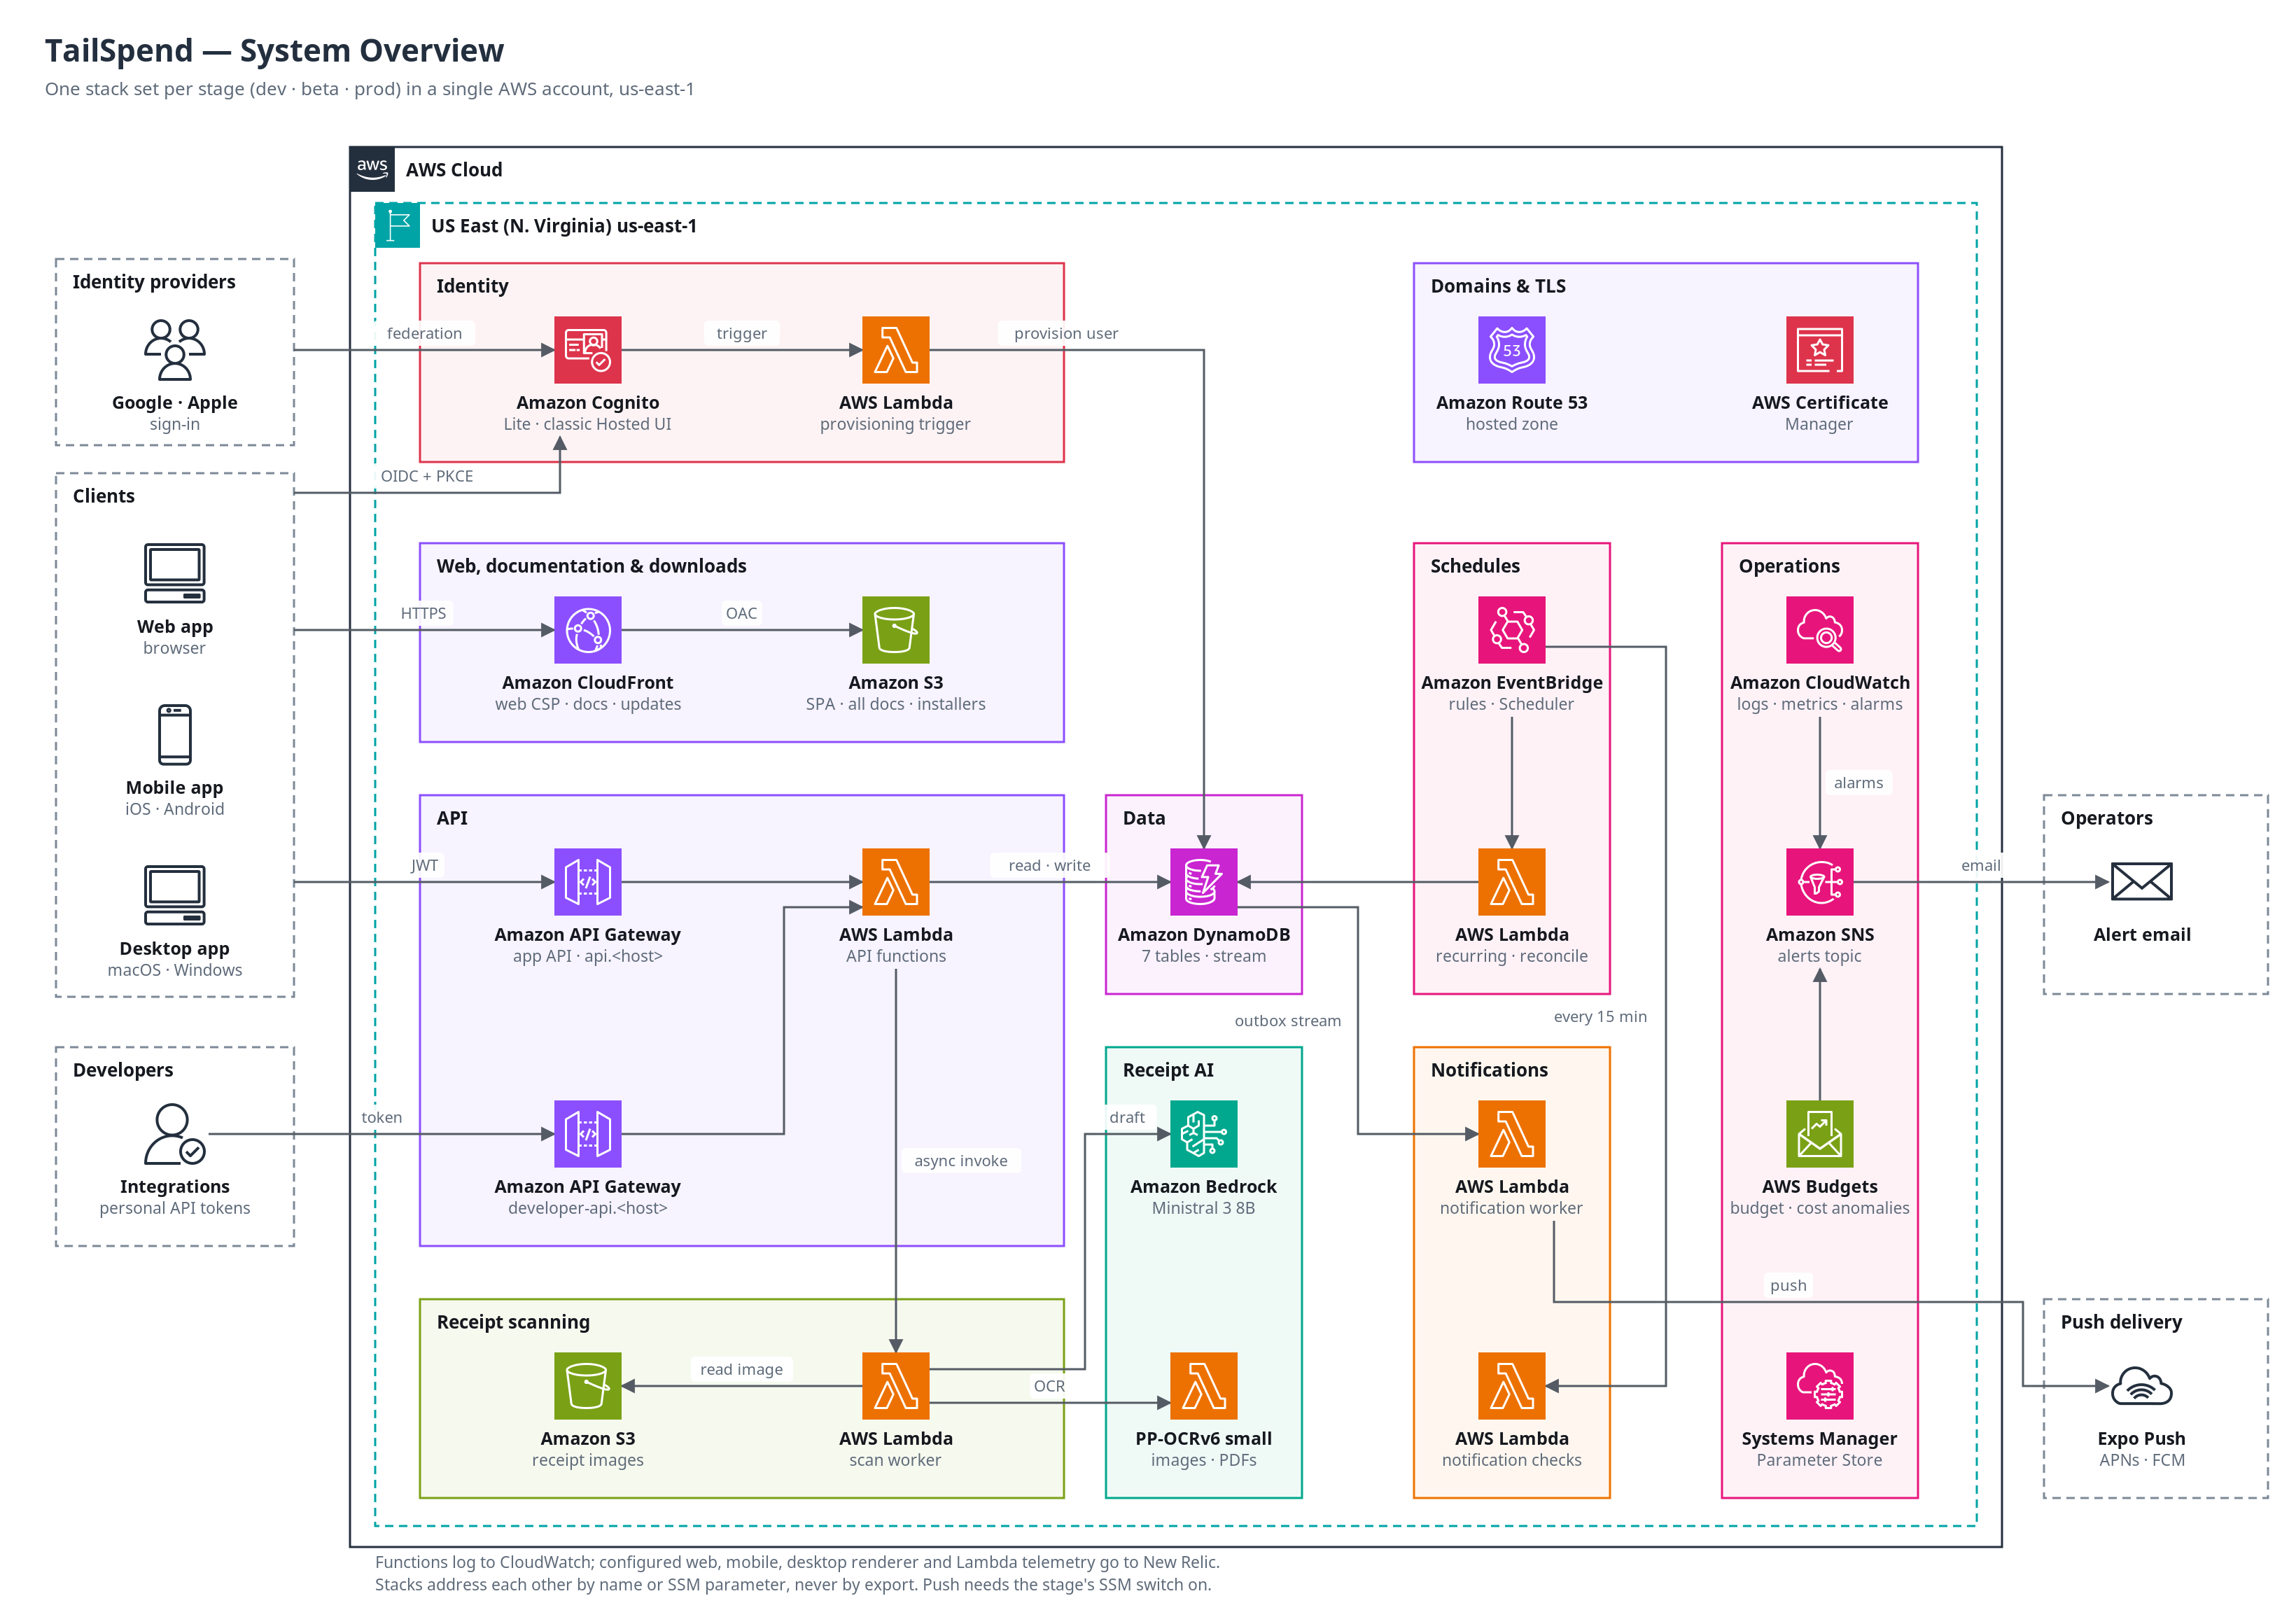
TailSpend is a Splitwise-style expense sharing product with stronger group controls and explicit spending limits. The system is split into three tiers:
- Clients: an Expo (React Native) mobile app, a Vite + React web app on AWS CloudFront + S3, and an Electron desktop app sharing the web UI
- API: two regional API Gateway REST APIs (app and developer), each fronting one core Lambda function that runs a shared router (see core-api.md)
- Data: Amazon DynamoDB tables, plus Amazon Cognito for identity
- Notifications: an in-app history for every account and opt-in mobile push, fed by outbox events on a DynamoDB stream (see notifications.md)
A single TypeScript monorepo (Turborepo) holds clients, services, infrastructure, and a generated API contract that is the source of truth across all tiers.
An optional receipt-scanning subsystem layers AI expense prefill on top of this base (PP-OCRv6 small image and rendered-PDF OCR + Ministral 3 8B on Bedrock, metered with ad-funded credits, backed by an S3 receipts bucket and a credit balance/ledger folded into the user table). It is additive and respects every contract above; see receipt-scanning.md for its design and plan.
High-level diagram
How a request reaches a function:
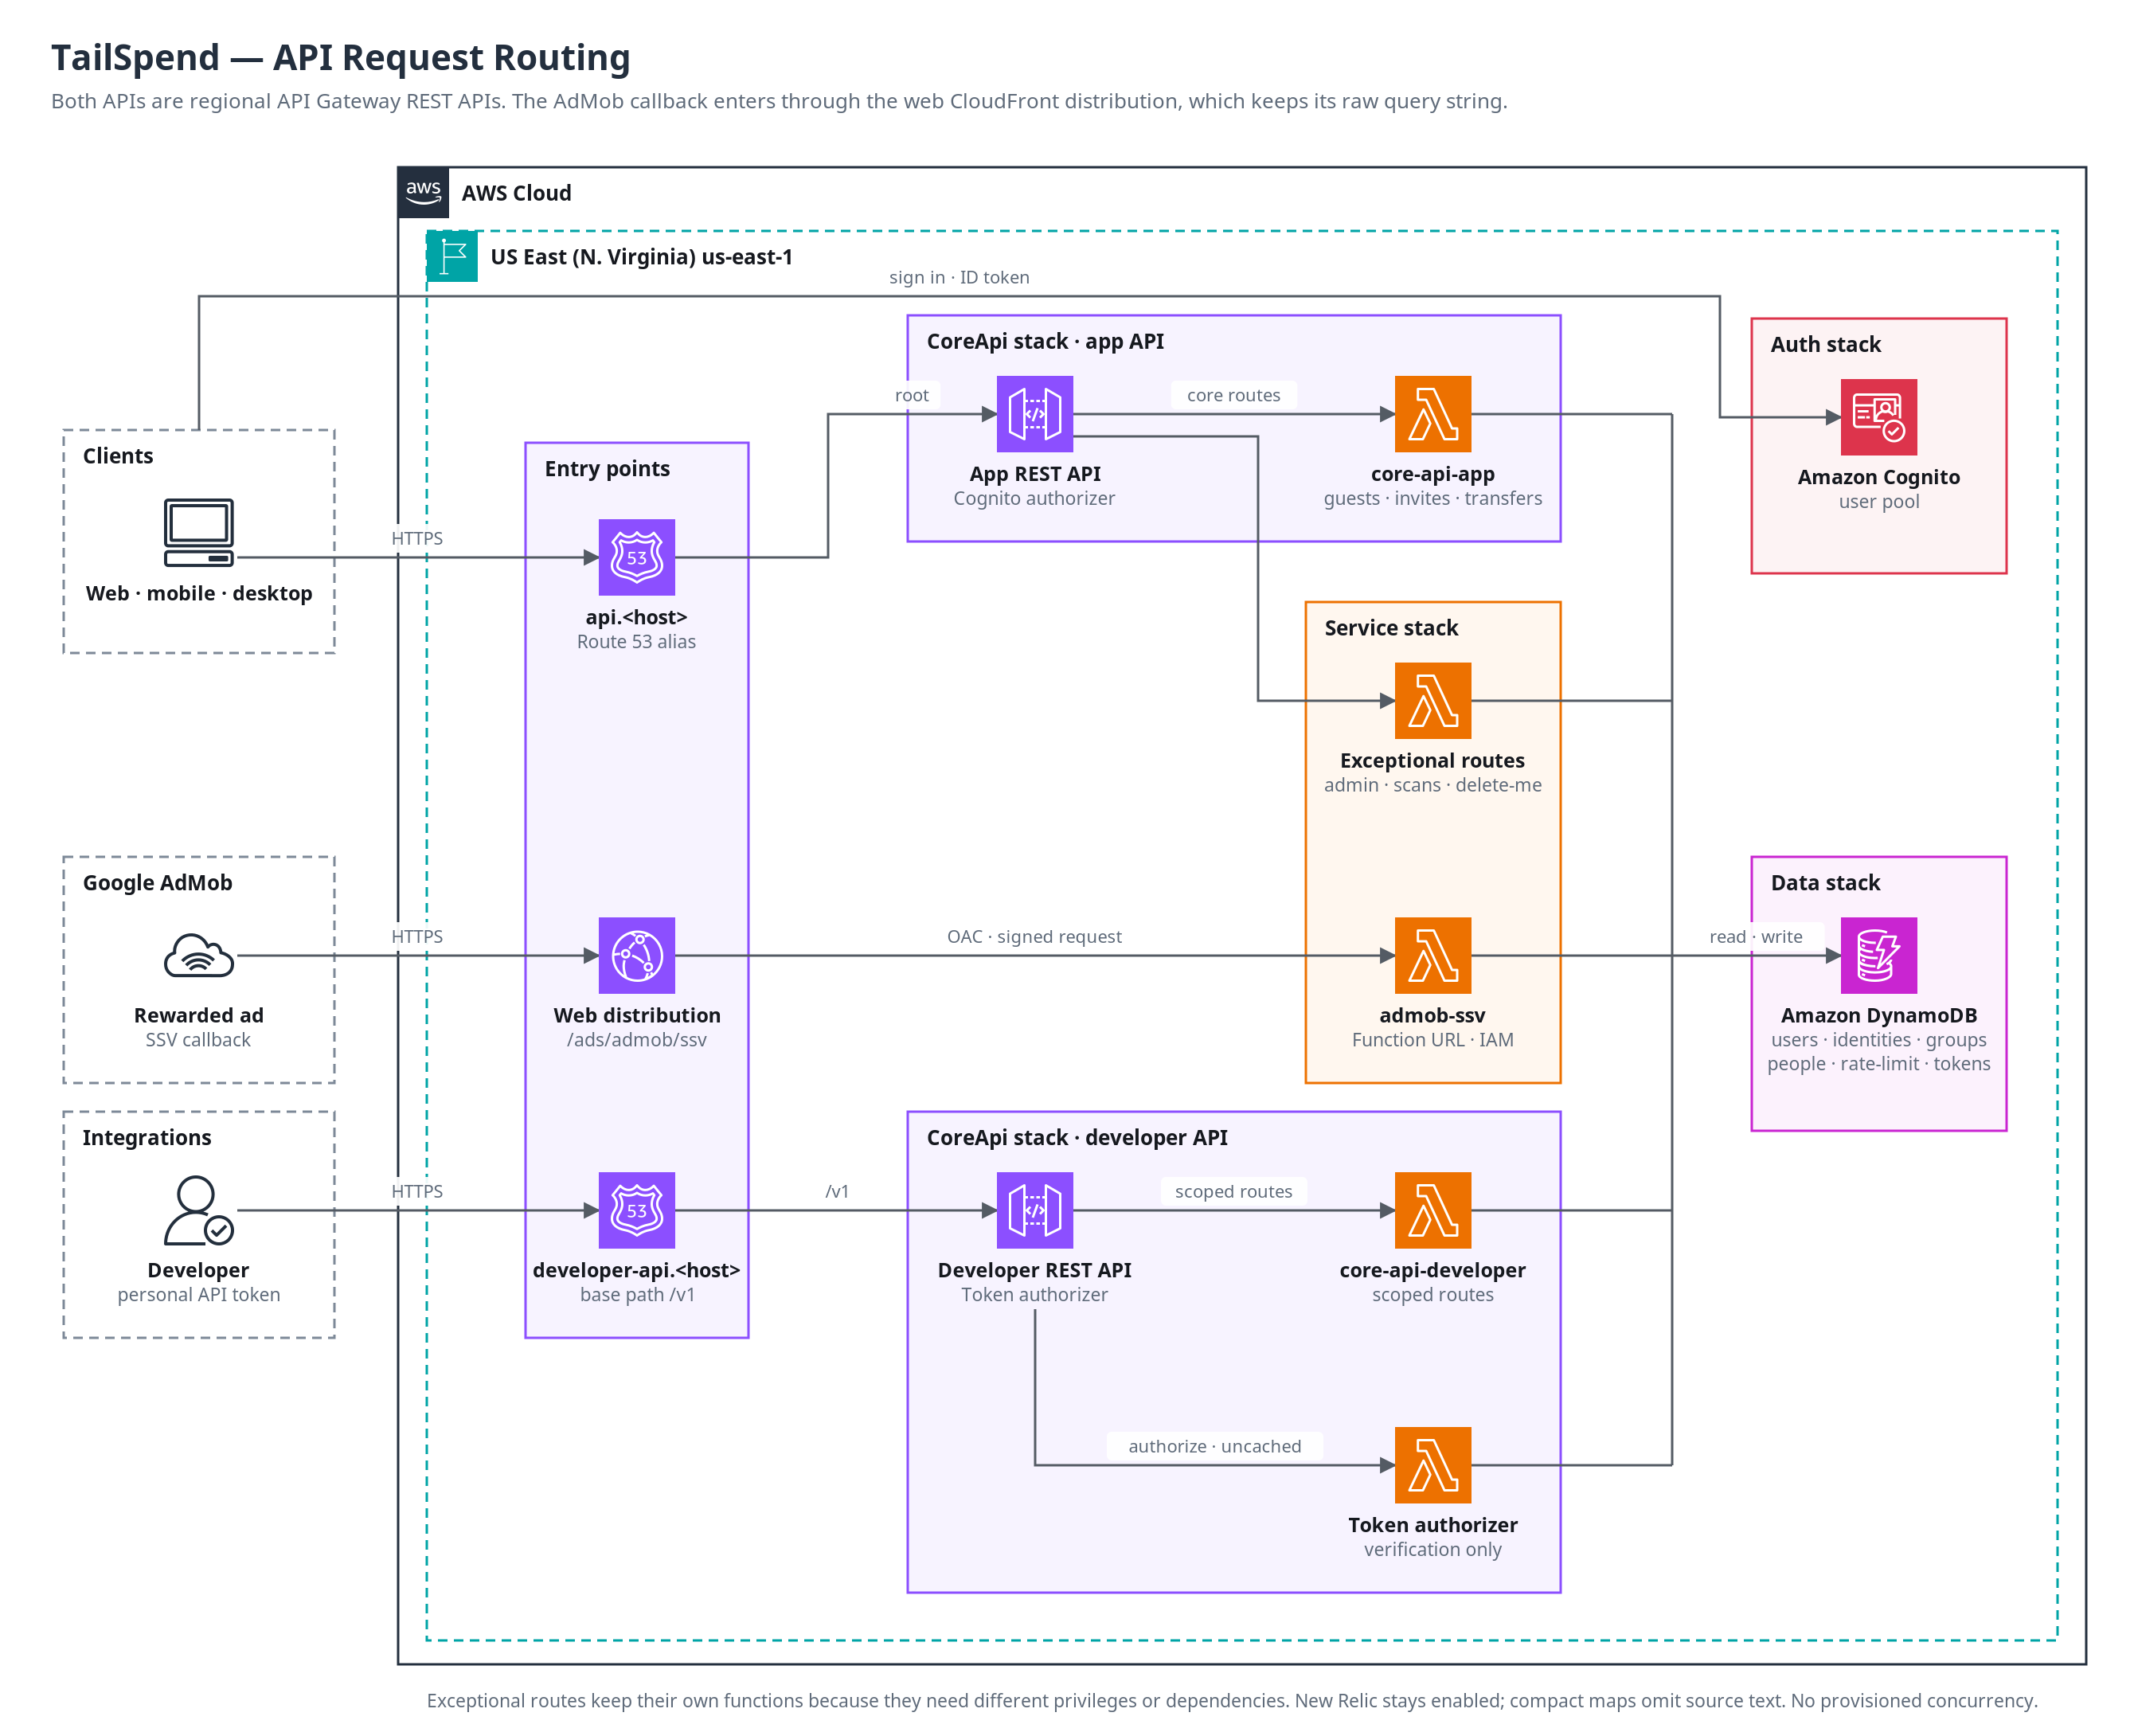
The uncached developer-token authorizer loads only verification dependencies; management/validation schemas stay in the core APIs. Service Lambda artifacts retain compact TypeScript source mappings without embedded source text. New Relic's slim layer and ESM wrapper remain enabled, with no provisioned concurrency. See the cold-start investigation.
Backend New Relic release tags use the last backend-affecting commit, resolved from full Git history in the deployment workflow. Web/docs/CI-only changes that leave backend and shared build inputs untouched therefore do not change Lambda environment configuration just to stamp a new deployment SHA. Shared build and lockfile changes are included conservatively; frontend release IDs remain the full deployment commit.
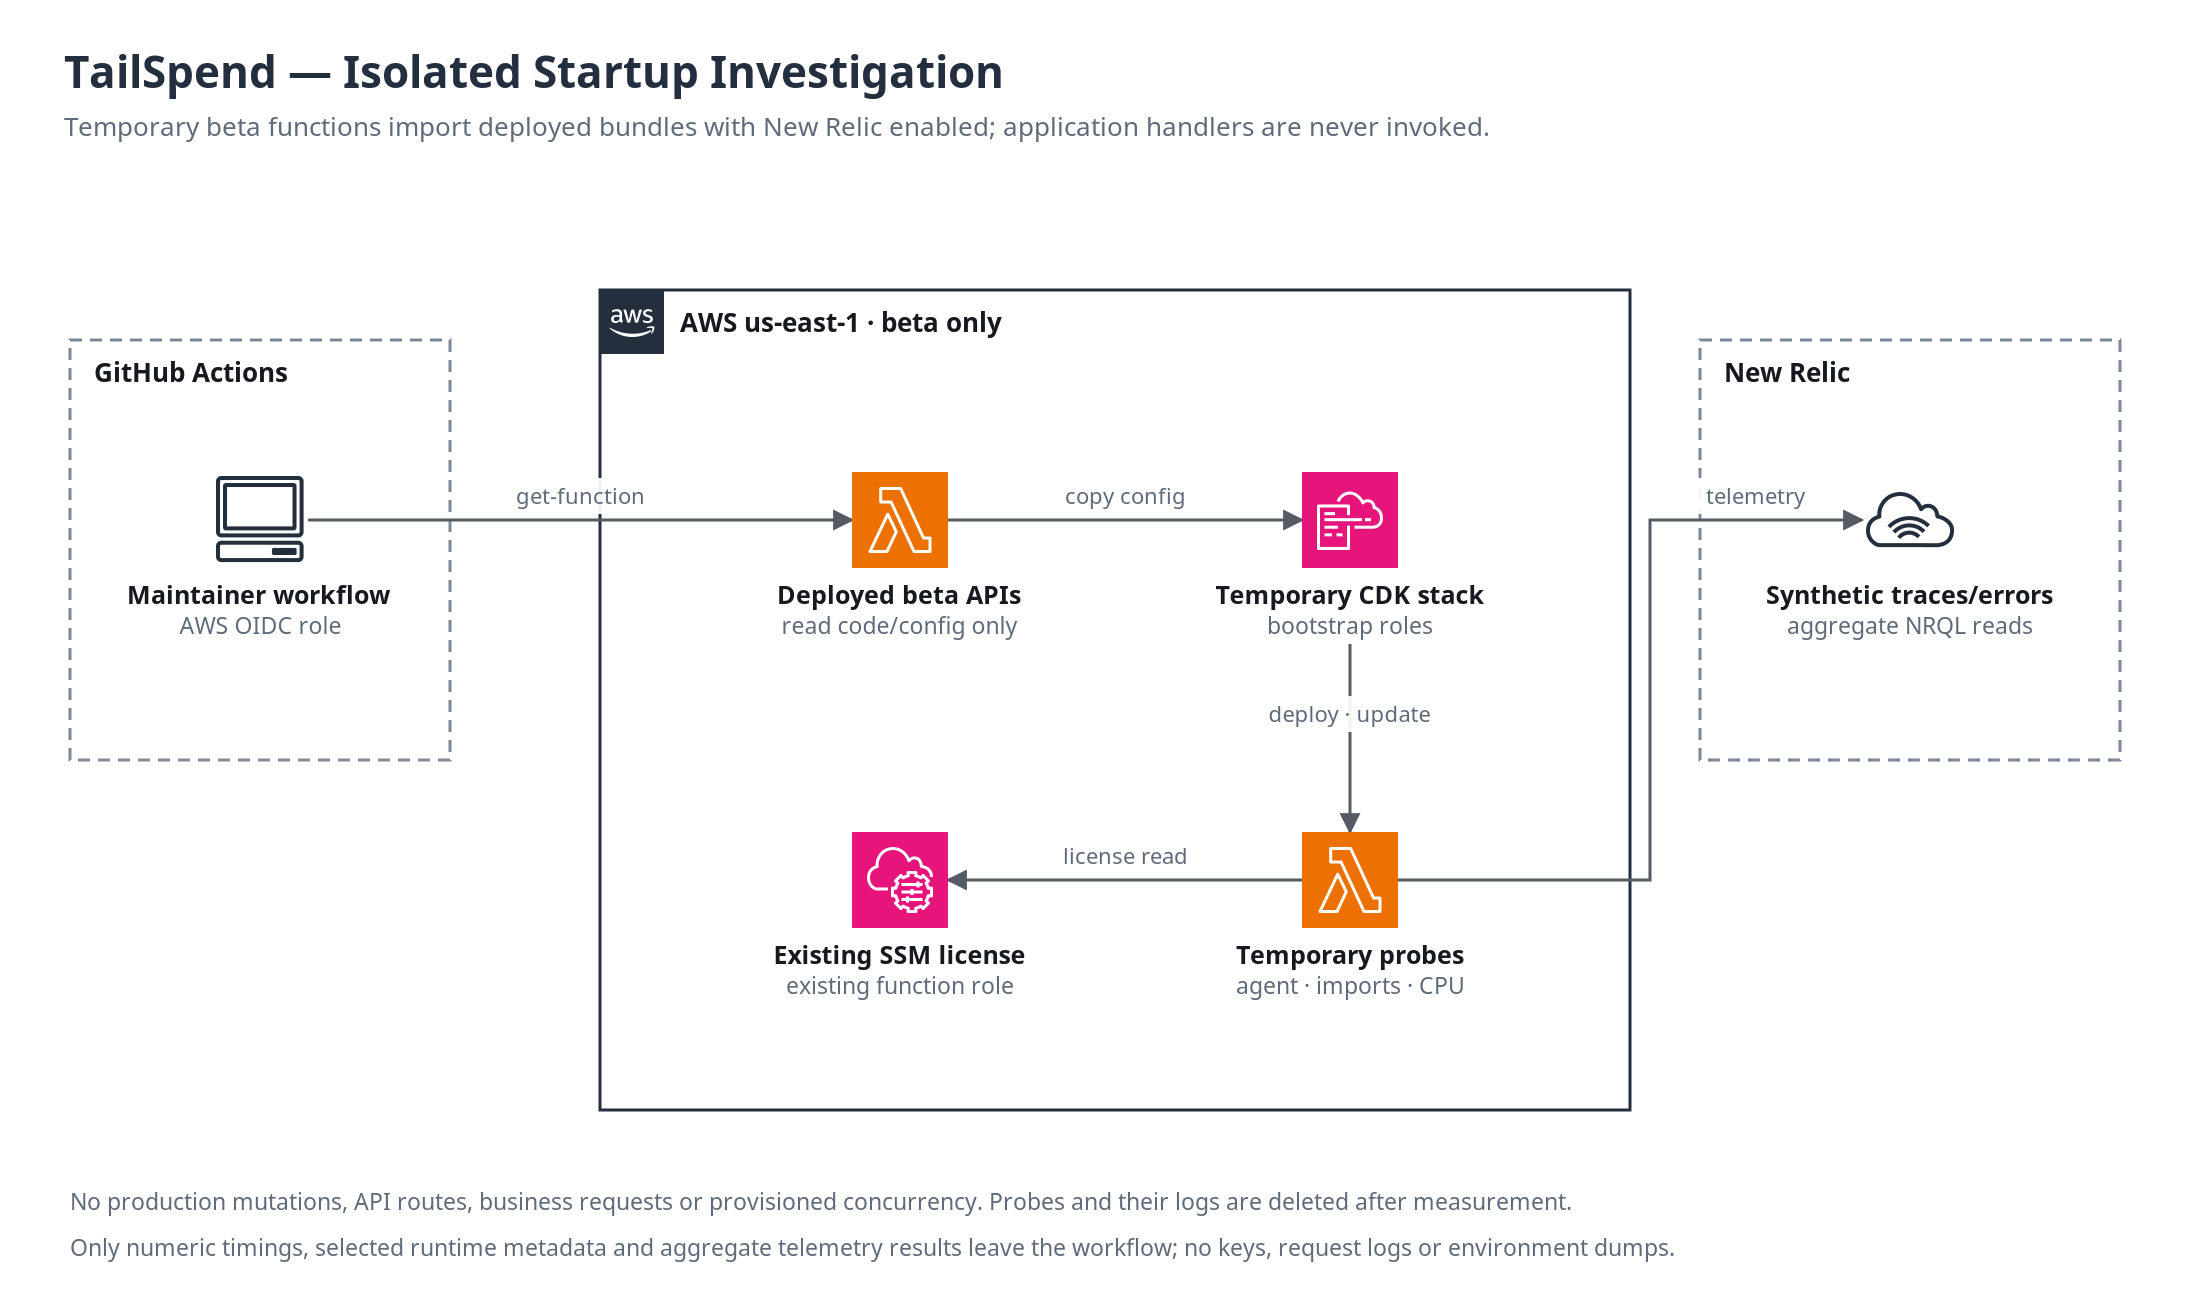
The optional startup investigation workflow copies deployed beta bundles/configuration into temporary, unexposed Lambda functions using the existing beta execution roles. They retain New Relic's layer, wrapper and SSM licensing, import application modules without invoking business handlers, and compare CPU allocations. The probe stack and its logs are deleted after measurement, with an additional workflow cleanup step. Only numeric timings and aggregate telemetry results are retained for two days. Production functions and API routes are not modified.
How notifications are recorded and pushed (see notifications.md):
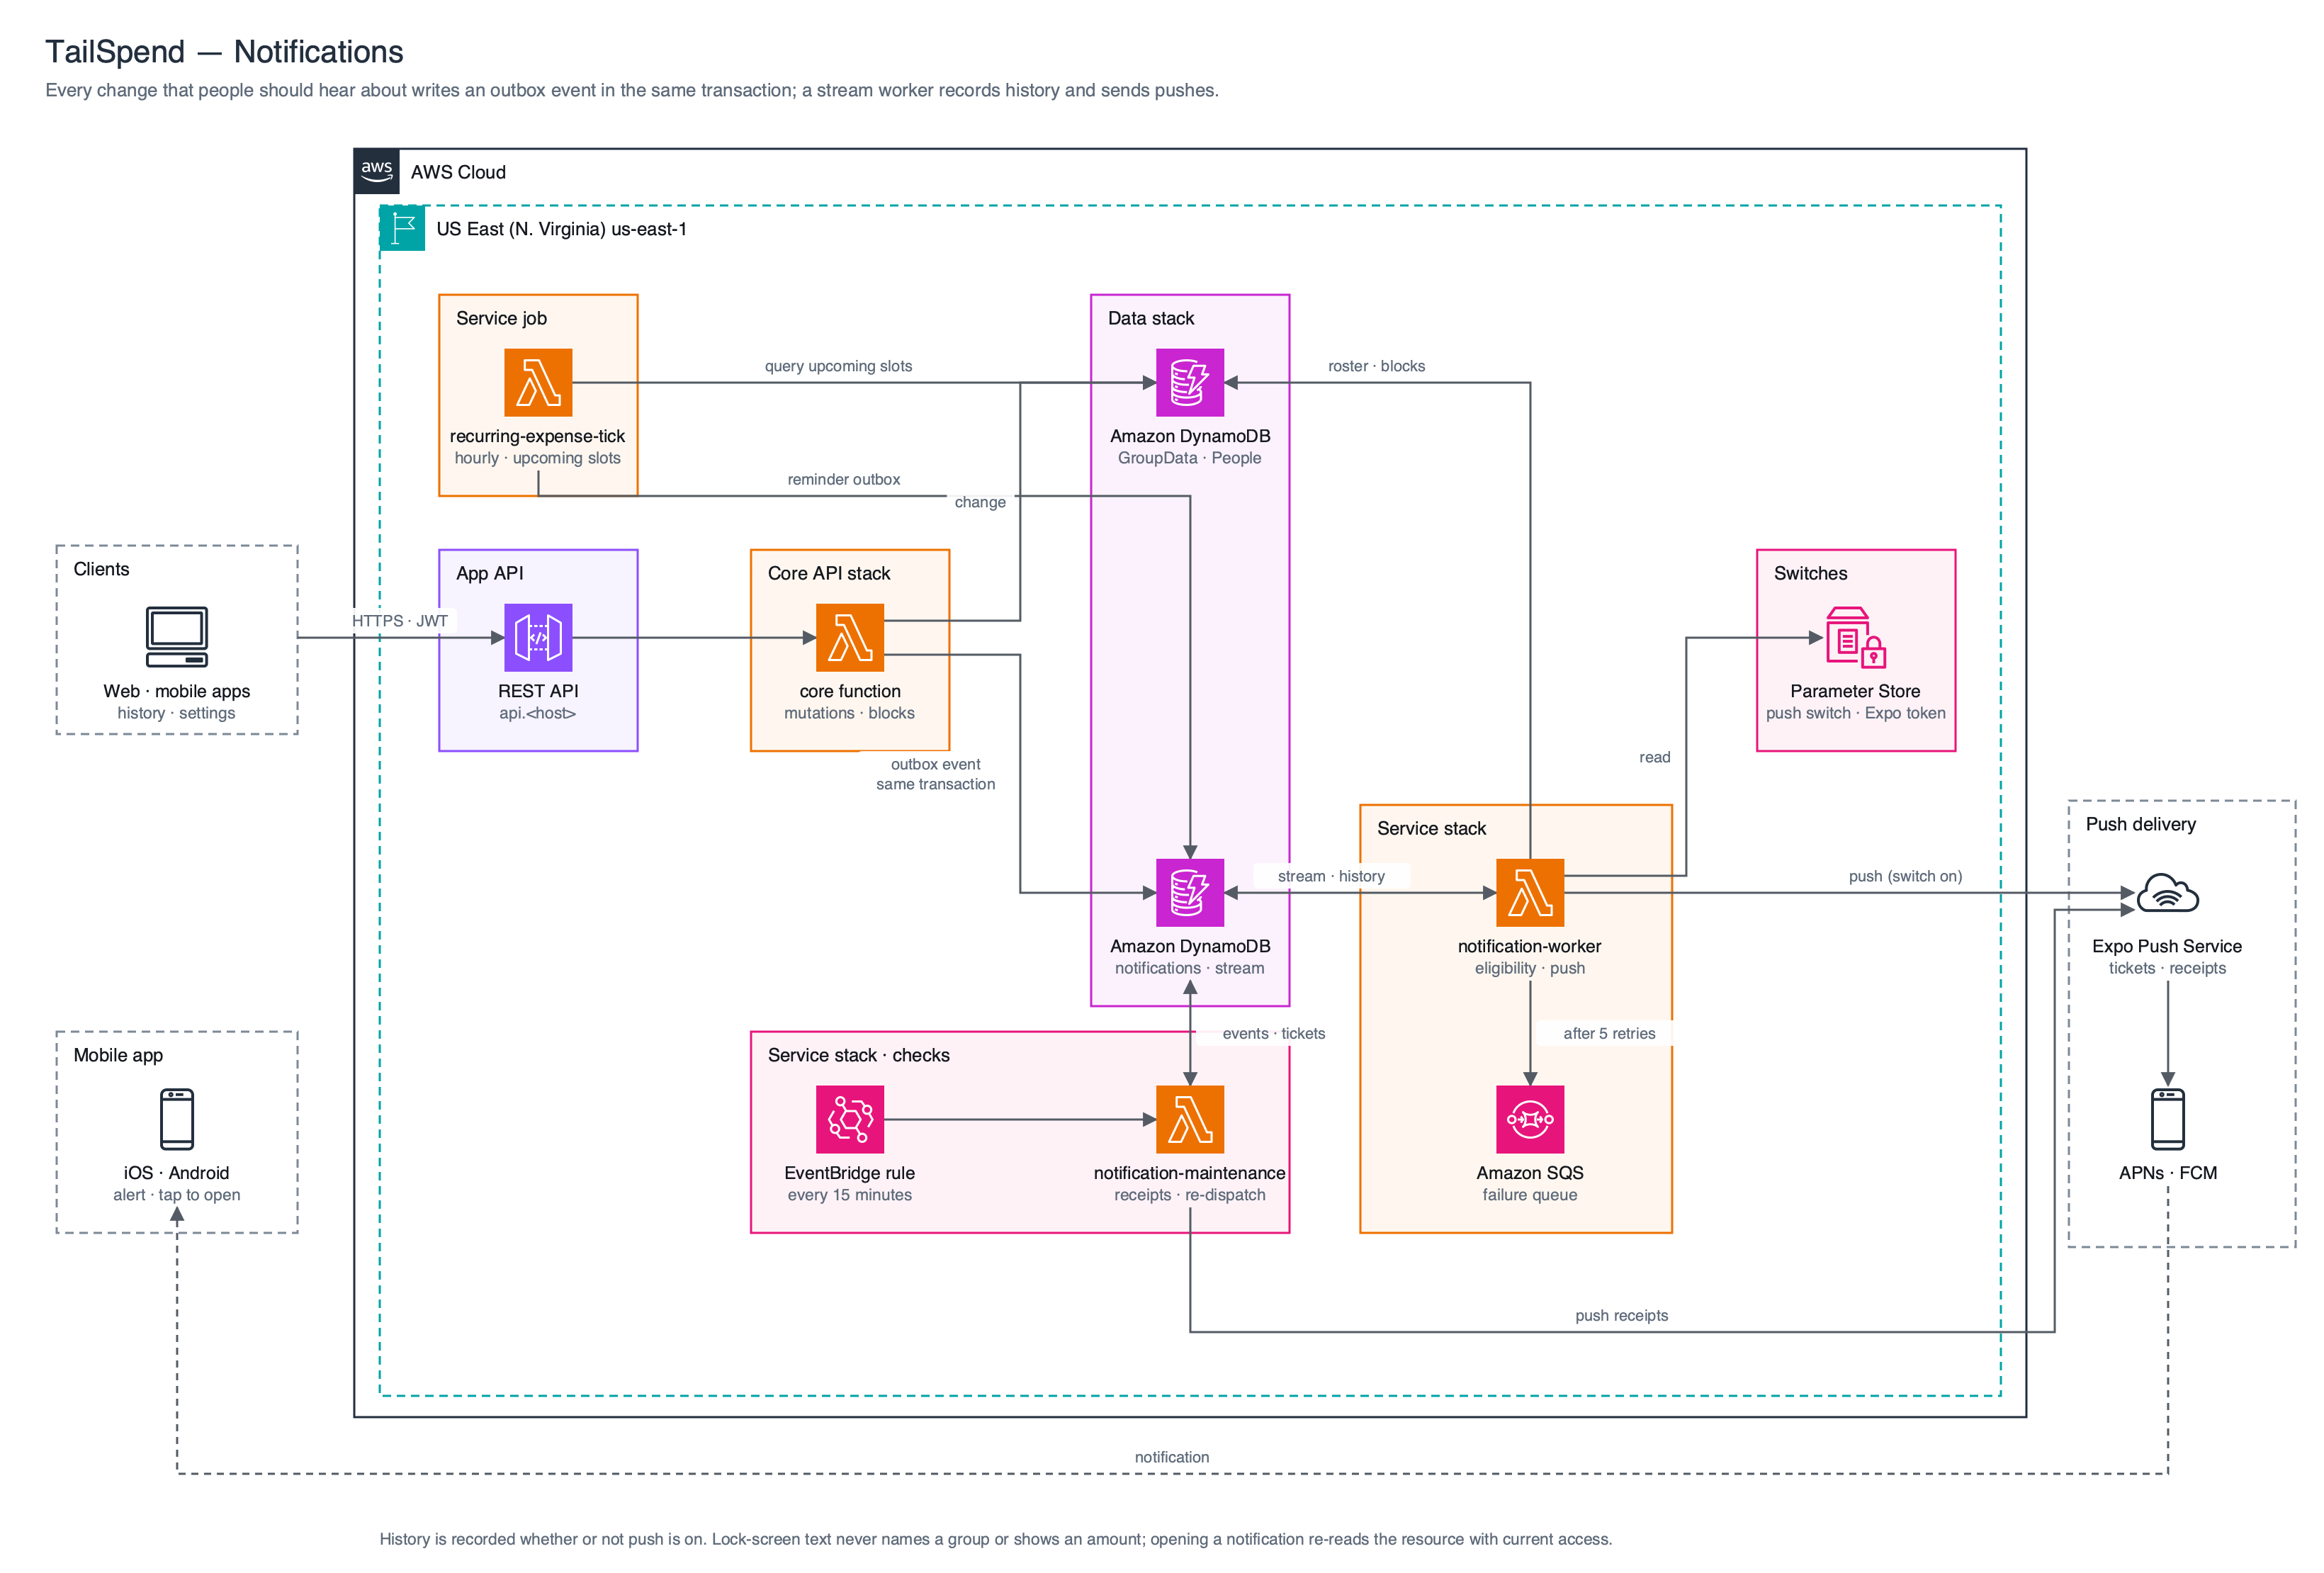
The diagrams are generated from diagrams/; edit the source and re-render rather than editing the images.
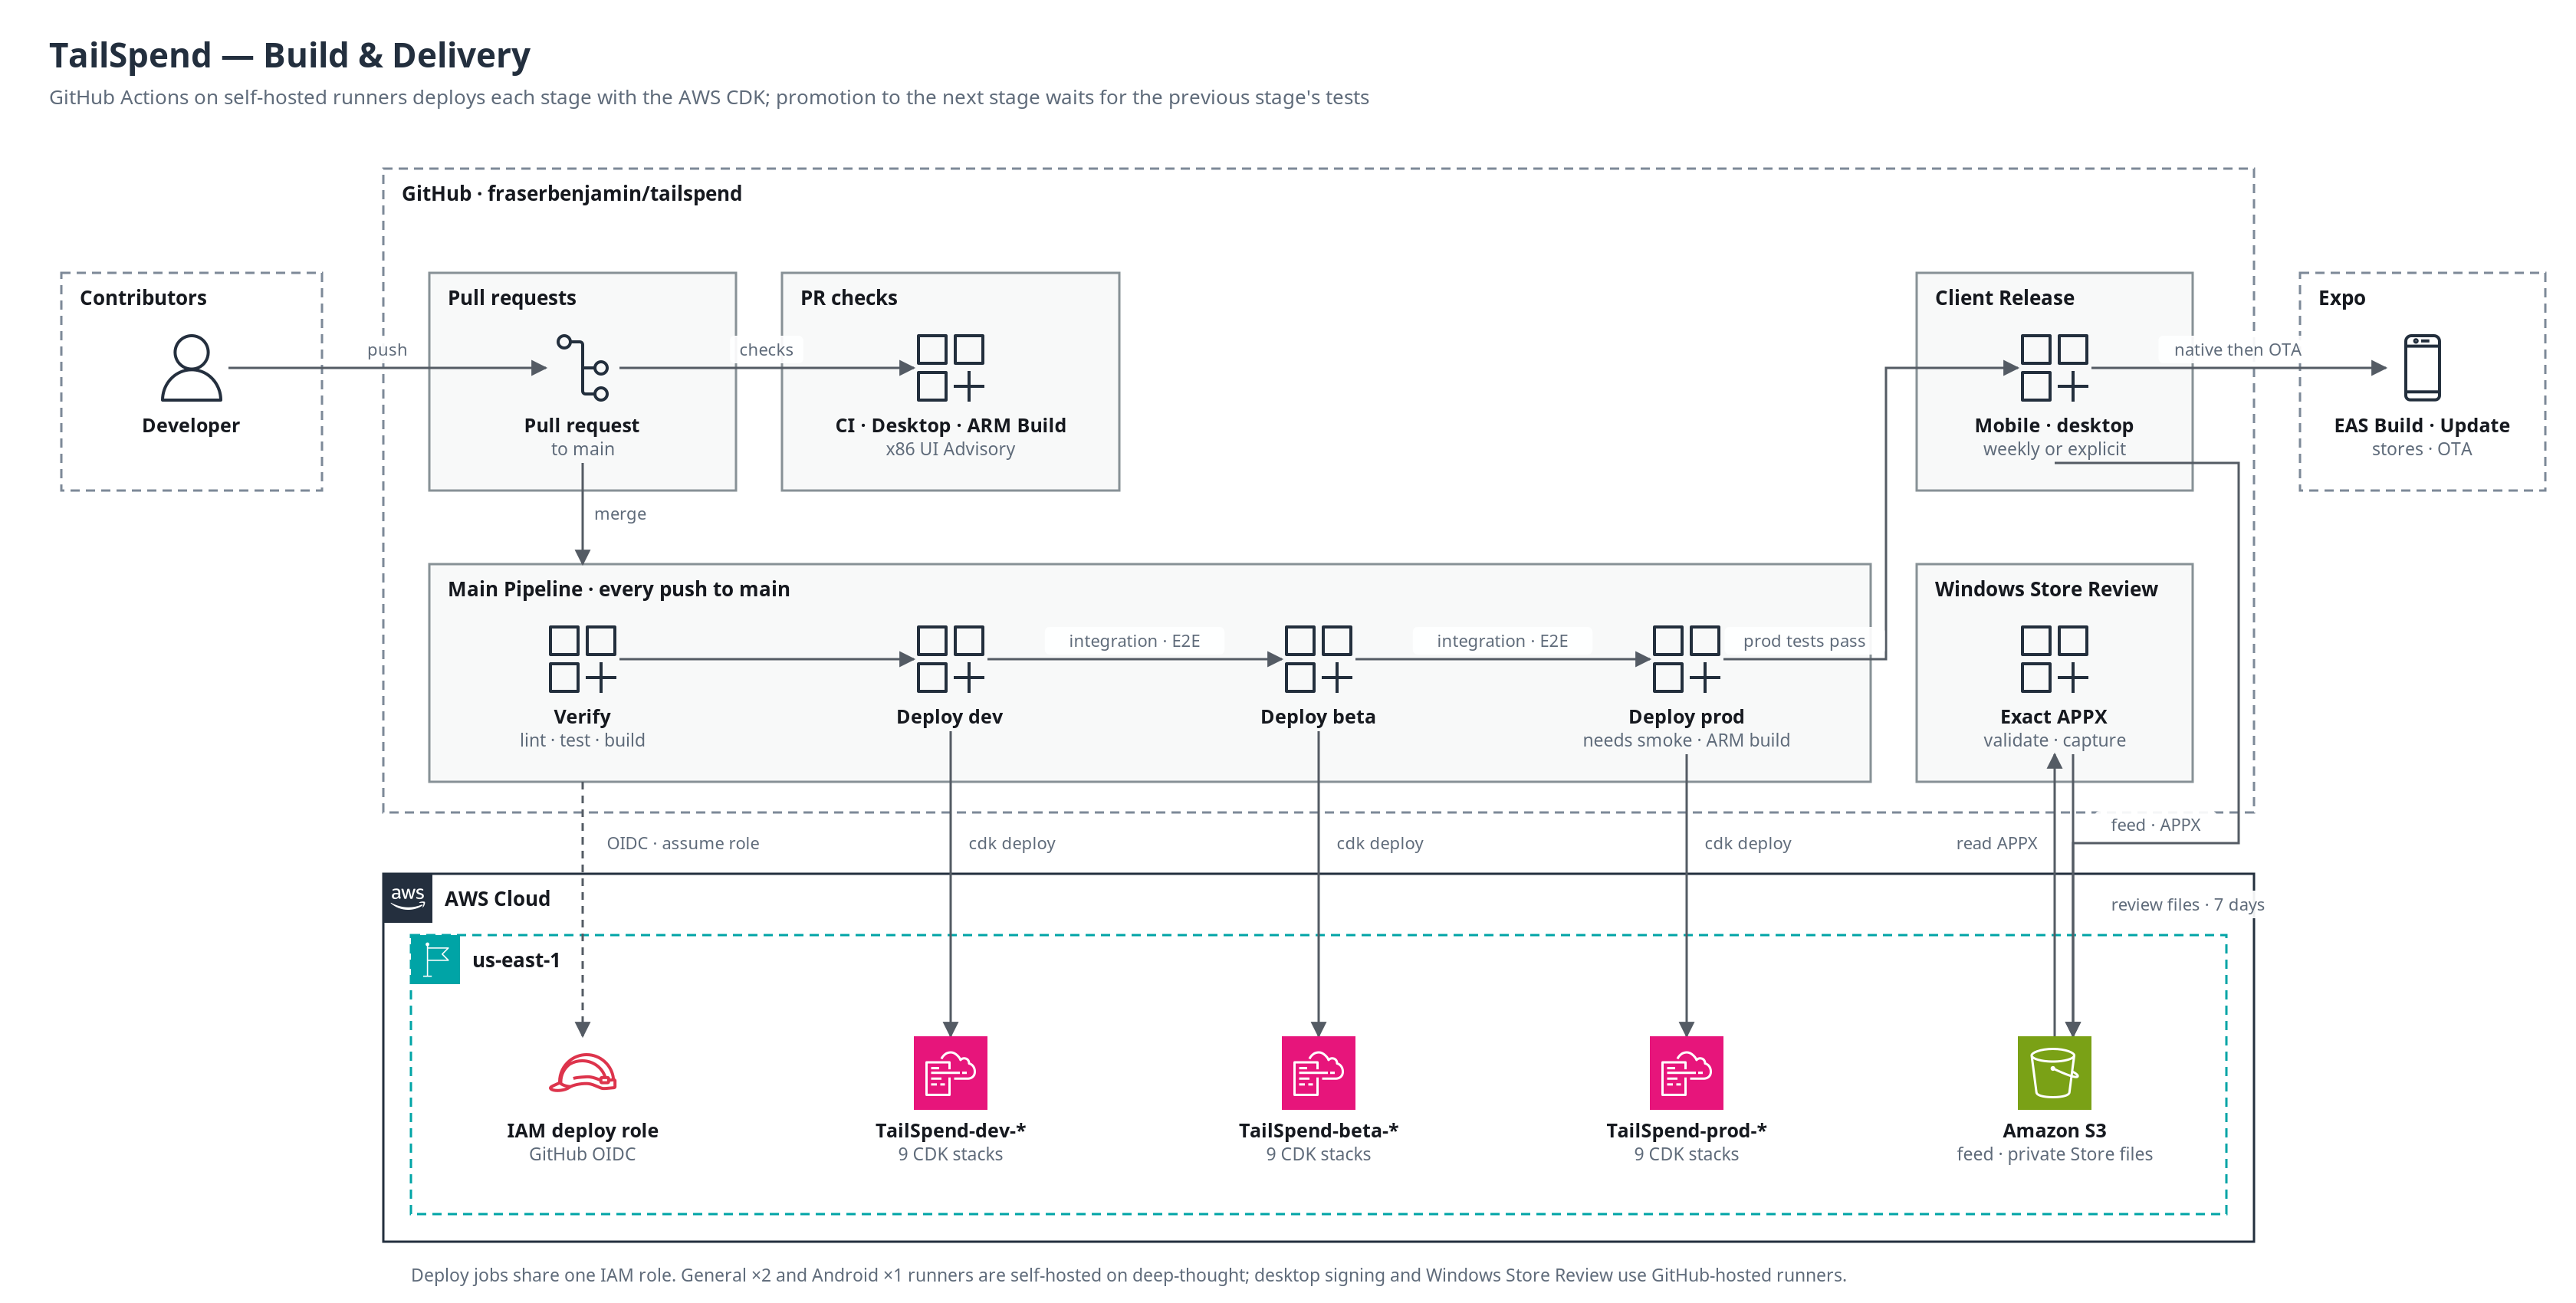
An explicit [client-release] main commit extends the verified production
pipeline to all changed clients. The same commit is used for native builds,
store submissions, OTA publication and desktop installers; native completion
gates OTA. Android compilation prepares bounded, regenerable Gradle cache space
while retaining the required ARM gate. See delivery.
For native release recovery, [client-release] [local-android] builds the
production Android bundle on the existing Android runner with EAS-managed
signing credentials, while iOS uses EAS cloud. Both results gate OTA publication
and the native released tag. The default remains cloud builds for both platforms.
Guest and Invitation Lifecycle
All clients use stable participant IDs for expenses. An invitation reserves an assignable guest in GroupData and records its ID in People in one transaction; acceptance consumes that invitation and claims the same participant with its unique account membership. Shared-link guest claims retain owner approval and cannot take an active invitation's reservation. Bulk history transfers lock the source, move expenses, settlements and recurring templates with concurrency checks, and remove/unlock the source only on completion. Financial writes check participant existence and transfer state transactionally. This reuses the current core API and tables; see the user flow and persistence rules.
Component responsibilities
Clients
| Client | Stack | Hosting | Purpose |
|---|---|---|---|
| Mobile | Expo SDK + React Native + TypeScript | EAS for builds, App Store / Play Store for distribution | Primary day-to-day app for capturing expenses and settling up |
| Web | Vite + React + TypeScript | AWS CloudFront + S3 (per-stage bundle) | Sign-up landing, group dashboards, settle-up flows, settings |
| Desktop | Electron + Vite + React + TypeScript | macOS installers / Microsoft Store | Shared app UI with native auth, window controls and updates |
| Docs | Generated static HTML + Swagger UI | AWS CloudFront + private S3 (per stage) | Help, repository documentation and API references |
All app clients consume the typed @repo/api-client package (generated from the OpenAPI spec) so request and response shapes stay aligned with the server.
Authentication is OIDC against Cognito. The clients perform the Authorization Code flow with PKCE against the Cognito Hosted UI and store tokens with the platform's secure store (Keychain / Keystore on mobile, the shared browser auth store for the web app).
The web CloudFront distribution enforces a Content-Security-Policy on every response, including SPA fallback pages. Scripts and fonts load only from the app's origin; connections are limited to that origin, generated blob URLs for exports, the stage's app API and Cognito domain, the fixed New Relic beacon host and the stage's regional receipts bucket for presigned uploads. Images are local, data or blob URLs. Inline React/Radix positioning styles remain allowed, while inline scripts, eval, objects, frames, base URL overrides and form posts are blocked. Web startup selects Zod's non-JIT parser, then dynamically imports the application bootstrap so Vite's shared schema chunks cannot execute before that configuration. New Relic's npm-installed lazy chunks remain local, so its CDN needs no script exception.
The desktop renderer loads the same optional @repo/browser-monitoring agent
as web, using its own New Relic application id from the stage's SSM config.
Renderer errors, page/navigation timing and API timing go directly to New Relic;
API requests carry distributed-tracing headers. The desktop CSP pins connections
to its API and Cognito origins and bam.nr-data.net. Telemetry identifies the
desktop platform, stage and checked-out release, with local installation paths
and credential query values redacted. See observability
for configuration and privacy limits.
Identity (Amazon Cognito)
- A per-stage User Pool (
TailSpend-{stage}), explicitly pinned to the Lite feature plan and classic Hosted UI, federated with Google and Apple. These flows and token revocation do not require Essentials. Beta and prod were verified on classic branding version 1 with password-only first-factor policy, MFA off, no threat protection and no pre-token-generation customization on 17 October 2026; the plan change is an in-place configuration update. Email and OpenID scopes are required; onlyemailis mapped from the IdP profile (the pool carries no name attribute). - Sign-in is social-only. Direct username/password is disabled (except the operator-managed integration-test user).
- TailSpend application identity is its own UUID
UserId. A user is anchored to their upstream Google/Apple identity, not to a Cognito poolsub. On first sign-in the provisioning Lambda (apps/infra/lambda/cognitoCreate) persists three mappings in theIdentitiestable to the sameUserId:google#<google-provider-user-id>/apple#<apple-provider-user-id>— the durable anchor, parsed from Cognito's federatedidentitiesmetadata.cognito#<current-pool-sub>— the request-time lookup for tokens issued by the current pool.
- Identities are never linked by email. Because the upstream mapping is durable, replacing the Cognito pool (which issues fresh
subs) reconnects the same human to the same account via their provider identity — a later sign-in with a newsubbut the same upstream identity relinks rather than creating a new account. - The trigger is idempotent and concurrency-safe (conditional
attribute_not_existswrites); an identity already linked to a different user fails loudly and is never auto-merged. It is wired to both POST_CONFIRMATION (fires on first federated sign-up) and POST_AUTHENTICATION (every subsequent sign-in, plus password sign-ins), so a federated account is provisioned the moment it is created. - Non-federated/operator users (the integration-test user) carry no upstream identity and get a
cognito#<sub>mapping only. - The profile
DisplayNameis seeded from the email local-part and is editable viaPATCH /users/me. A rename fans out to the caller'sUSERparticipant rows in every group, so a group roster never shows a stale copy of the account name (see USER display-name sync). - Token verification at the API tier uses the Cognito JWT issuer and JWKS.
API tier (API Gateway + Lambda)
- Two regional API Gateway REST APIs (issue #632): the app API on
api.<stage>(Cognito user-pool authorizer) and the developer API ondeveloper-api.<stage>…/v1(personal-token authorizer). Methods are generated from the OpenAPI document produced by@repo/openapi. - Each API invokes one core Lambda function running the shared router in
apps/services/src/core/, which dispatches to the per-operation handlers. App and developer functions have independent IAM, configuration, limits and concurrency. See core-api.md and developer-api.md. - Exceptional routes keep their own functions: admin, receipt scanning and account deletion (behind the app REST API), and the AdMob SSV callback (a private function URL behind the web CloudFront distribution).
- Lambdas run Node 22 on ARM64. They are bundled with
NodejsFunction(esbuild + Docker) into ESM. - All Lambdas read DynamoDB table names from environment variables populated by CDK (
USERS_TABLE_NAME,IDENTITIES_TABLE_NAME,GROUPS_TABLE_NAME,DEVELOPER_TOKENS_TABLE_NAME,PEOPLE_TABLE_NAME,NOTIFICATIONS_TABLE_NAME). - Domain logic lives under
apps/services/src/{groups,expenses,participants,invite,join-requests,...}and is invoked by the route handlers inapps/services/src/handlers/. - The synth validator checks OpenAPI parity for the full authorization and grant registries.
EXCEPTIONAL_ROUTE_HANDLERSmaps only the eight separate Lambda entry points; core handlers are imported directly byservices/src/core/app-routes.ts. - Scan work is delivered by direct Lambda asynchronous invocation. The retired SQS scan queue and disabled polling mapping are removed; the live async worker's 14-day failure queue, two retries and 16-minute event-age limit remain. DLQ replay sends the original
ScanJobMessagebody to the worker; it does not wrap it in an SQSRecordsevent. All three retired queues were verified empty and disabled on 17 October 2026.
Authorization happens inside each Lambda by reading participant rows in the GroupData table (see database.md). A Query on the UserParticipantsIndex GSI resolves (authenticated UserId, requested GroupId) → ParticipantId, Role, and the role gates the action:
OWNERcan do everything in the group, including manage participants, toggle the public invite, and approve/deny join requests.MEMBERcan read the group and create/edit/delete their own expenses and comments.VIEWERis read-only.
Public invite reads are unauthenticated: clients hit /groups/{groupId}/invite/... without a JWT, the invite Lambda reads (<gid>, "INVITE") from GroupData, returns 404 if the row's Enabled flag is false, and otherwise serves a read-only view of the group. There is no token in the URL — the path itself is the capability, and OWNERs can disable the invite at any time. To turn into a participant, the visitor signs in and submits a join request, which an OWNER approves with a TransactWriteItems across the JOINREQ#… row and the PARTICIPANT#… row in GroupData (flipping a guest from GUEST to USER, or creating a fresh USER participant).
The core API reads People block edges before disclosing another user's public identity or accepting a join request. Join checks cover every current OWNER; the notification worker rechecks those edges before delivery. Denial atomically replaces the applicant's pending lock in GroupData with a persistent denial guard, preventing tokenless resubmission. A valid invite may replace that guard but cannot overwrite a pending request.
Data tier (DynamoDB)
DynamoDB tables, all on-demand billing. See database.md for keys, GSIs, and access patterns. The main ones are below; DeveloperTokens, People and Notifications (devices, preferences, history and the streamed outbox) are described there too.
UserData: a single-table layout keyed by(UserId, SK). It holds the user profile (SK = PROFILE) and is shaped so the receipt-scanning credit balance/ledger (SK = BALANCE,TXN#…,ADTXN#…) shares the sameUserIdpartition and reads in oneQuery.DisplayNameis editable viaPATCH /users/meIdentities:<provider>#<subject>→ internalUserIdmapping, where provider isgoogle/apple(durable anchor) orcognito(request-time lookup). It stays separate because it sits on the strongly-consistent JWT-verification hot path. A user has multiple rows — one per linked identity — all pointing at the sameUserId.UserIdentitiesIndexGSI onUserIdlists every identity linked to an accountGroupData: a single-table layout keyed by(GroupId, SK)that holds every per-group entity in oneGroupIdpartition, distinguished by sort-key prefix and anEntityTypeattribute:- Group head (
META), invite settings (INVITE), and join requests (JOINREQ#<requestId>), plus a per-applicantJOINREQ-PENDING-LOCK#…enforcing at-most-one pending request - Net balances (
BALANCE#v1) → transactionally maintained participant net amounts and activity counts; initialized dashboard reads use two BatchGets after the membership query. Legacy migration publishes guarded snapshots only after old writers drain. - Participants (
PARTICIPANT#<participantId>) →Type(USERorGUEST) +Role(OWNER,MEMBER, orVIEWER); guests have noUserIduntil claimed. SparseUserParticipantsIndexGSI onUserIdanswers "what groups am I in?". ExpensePaymentsand item splits referenceParticipantId, so claiming a guest never rewrites historical expenses - Expense head (
EXPENSE#<id>#0#META) and comment (EXPENSE#<id>#1#COMMENT#<ts>#<id>) rows; a sparseGroupExpensesIndexGSI for paging expenses, andExpenseIdIndexfor cross-group lookups - Recurring-expense templates (
RECURRING#<id>); a sparseDueRecurringExpensesIndexGSI surfaces ACTIVE rows due now - Two sparse GSIs —
PendingJoinRequestsIndexandUserPendingJoinRequestsIndex— surface onlyStatus = PENDINGjoin requests; decided rows persist on the base table for audit but drop out of both indexes
- Group head (
Comments are first-class rows in the same partition as their expense. A single Query returns the expense and its full thread; concurrent comment writes don't contend on a list attribute, and individual comments can be edited or deleted as standalone items.
Receipt scanning & credits
The receipt-scanning subsystem lets a user photograph or upload a receipt and have an expense draft prefilled by AI, metered with ad-funded credits. It introduces:
- A scan job worker that validates the S3 upload and invokes a separate
PP-OCRv6 small image OCR container Lambda (2 GiB x86_64, pinned ONNX
weights, no runtime downloads). PDFium renders PDF pages sequentially in that
same helper, with page-count, size, resolution and aggregate text limits.
Textract is removed from the serving path and IAM grants.
The worker structures OCR text with Ministral 3 8B Instruct on Bedrock
(
mistral.ministral-3-8b-instruct, native structured output) into a draft matchingCreateExpenseRequest. The draft prefills the existing create-expense form — scanning never writes an expense directly. - A credit balance + append-only ledger (atomic mutations) folded into a
reshaped
UserDatasingle table — the existingUserstable gains a sort key so profile and credit rows share aUserIdpartition (Identitiesstays separate; it's on the strongly-consistent auth hot path). Plus an S3 receipts bucket (private, SSE, short lifecycle expiry, presigned direct upload). Credits are earned via AdMob rewarded video (mobile only) and granted by a signature-verified server-side-verification callback, never by the client. - New routes wired through the same generated-OpenAPI + three-registry discipline, and an extension to the per-route grant model so a Lambda can be granted least-privilege S3 / OCR Lambda / Bedrock access alongside its DynamoDB grants.
The #694 replacement is implemented in source but not deployed. Its Python helper reads only receipt objects and has no model or user-table access. The 1 GiB Node worker still bills while awaiting OCR/Bedrock; Step Functions is a separate orchestration follow-up. PDF rendering now runs locally; representative PDF financial accuracy and deployed Lambda timings still require evaluation.
Full design, data model, and phased plan: receipt-scanning.md.
Notifications
Expense creation/edits/deletion, settlement, join-request, structured comment mention, friend-request and direct-invitation writes add an outbox EVENT row to the Notifications table in the same TransactWriteItems as the change. The table's stream (filtered to new EVENT rows) invokes the notification-worker Lambda, which works out recipients from the current roster, writes one history entry per recipient, and sends pushes through the Expo Push Service (APNs / FCM) when the stage's SSM switch /tailspend/<stage>/notifications/push-enabled is true. Records that keep failing go to an SQS failure queue. A scheduled notification-maintenance Lambda (EventBridge, every 15 minutes) checks Expo push receipts and re-dispatches events the stream missed. The hourly recurring-expense job conditionally adds one reminder per upcoming template/slot within 24 hours. Dispatch rechecks current membership, pending People state and account/category/group preferences; mutes preserve history. People balance reads report request-scoped latency and DynamoDB read capacity to New Relic. Full design: notifications.md.
Infrastructure & build
apps/infrais an AWS CDK app with nine stacks per stage (seeapps/infra/main.ts):WebStack: the web SPA's private S3 bucket + CloudFront distribution (which also serves the AdMob SSV callback at/ads/admob/ssv), and the SPA host's DNS alias that other stacks' custom domains depend on. A separate bucket deployment serves the mobile Universal Links / App Links verification documents under/.well-known/as JSON before the root deployment invalidates the cache; see mobile link verification.DataStack: DynamoDB tables and GSIs, plus the notifications table's stream (its ARN is published to SSM forServiceStack)MediaStack: the private S3 receipts bucket for receipt scanningDesktopUpdatesStack: the private S3 bucket + CloudFront feed the Electron app's auto-updater polls. Release cleanup keeps three macOS installer versions per architecture and every artifact referenced by the live feed, scoped to the released stage. Noncurrent S3 versions expire after 30 days. Itsstore-submissions/prefix holds Microsoft Store APPX packages and exact-package review screenshots/validation reports for 7 days and is denied to CloudFront. Windows Store Review writes its four result files beside the source APPX using the existing GitHub OIDC publisher role; its summary links to the private directory without relying on Actions artifact storage.AuthStack: Cognito User Pool, Google and Apple IdPs, Hosted UI domain, app clients, post-authentication/confirmation LambdaCoreApiStack: the app and developer REST APIs, their two core functions and the developer-token authorizer (seecore-api.md)ServiceStack: theapi.<host>domain (mapped to the app REST API), the exceptional per-route functions, the scan worker and reconciler, the notification worker (stream event source + failure queue) and maintenance job, and the other scheduled jobs. It deploys afterDataStack, as doesCoreApiStackMonitoringStack: the alerts SNS topic and, in prod only, the CloudWatch alarms, the account budget and cost anomaly detectionApiDocsStack: static help, repository documentation and API references on CloudFront + private S3
The stacks are decoupled — each reaches DynamoDB tables and the receipts bucket via literal
tailspend-{stage}-{…}names/ARNs rather than cross-stack imports — so a table or bucket can be reshaped without an "export in use" deadlock.Turborepo orchestrates builds and caches across packages.
The API contract is generated, not hand-written:
- Zod schemas in
packages/api-schema/srcare the source of truth. @repo/openapiproducespackages/openapi/dist/openapi.jsonandapps/infra/dist/openapi.json.ServiceStackreads the OpenAPI document to generate routes.@repo/api-clientregenerates a typedopenapi-fetchclient used by both clients.
- Zod schemas in
Deploys are CDK-driven from
apps/infra; its normal Turbo build pulls in the OpenAPI generator first.
Environments
| Environment | Stage tag | Notes |
|---|---|---|
dev |
dev |
Per-developer or shared, deployed manually from a workstation |
prod |
prod |
Single production account, currently us-east-1 |
Stage drives DynamoDB table names (tailspend-{stage}-{table}) and Cognito domain prefixes. Future work: split AWS accounts per environment and move deploys behind GitHub Actions.
Cross-cutting concerns
- Validation: every Lambda parses its incoming payload with the relevant Zod schema from
@repo/api-schemabefore calling into services. Internal service code only receives typed values. - Money: amounts are integers in the smallest currency unit (cents, pence). Currency conversions between an expense currency and a group currency are stored explicitly as
amount(expense currency) andcharge(group currency) on each payment. - Identity in domain data: every actor or referenced person in a group is a
Participantwith a stableParticipantId. A guest is a participant withType = GUESTand no Cognito account; an OWNER approving aTAKEOVER-mode join request flips the same row toType = USERwith aUserIdattached, so historical expenses don't need rewriting. - Authorization: handled at the application layer through the Participants table. Every group has at least one
OWNER. A request is authorized by resolving(authenticated UserId, requested GroupId) → ParticipantId, Rolevia theUserParticipantsIndexGSI and applying a role check (OWNER,MEMBER,VIEWER). Public invite reads are gated by the per-groupINVITE.Enabledflag — possession of the URL is the capability, but the OWNER can revoke that capability at any time by toggling the flag. - Observability: CloudWatch logs per Lambda. Structured logging and tracing are planned but not yet wired up.
- Secrets: Google OAuth credentials and Apple Services ID/key credentials are required at deploy time. They are loaded by the CDK app from environment variables; production should move them to Secrets Manager.
Repository map
tailspend/
├── apps/
│   ├── web/             # Vite + React SPA (CloudFront + S3)
│   ├── mobile/          # (planned) Expo app
│   ├── services/        # Lambda handlers + domain services
│   └── infra/           # AWS CDK app
├── packages/
│   ├── api-schema/      # Zod schemas (source of truth)
│   ├── openapi/         # generates OpenAPI JSON from api-schema
│   ├── api-client/      # generated typed client (openapi-fetch)
│   ├── ui/              # shared React UI primitives
│   ├── eslint-config/
│   └── typescript-config/
└── docs/
    ├── architecture.md  # this file
    ├── api.md           # API reference
    └── database.md      # DynamoDB schema and access patterns
Native Release Validation
Both mobile platforms retain Expo's default Hermes V1. Android shipping binaries contain only ARM32/ARM64 libraries. The native workflow requires ARM compilation and packaged-ABI checks on the Intel build host; its x86 emulator UI suite is advisory because that architecture is outside the app's shipping support scope. ARM runtime/push/OCR and iOS acceptance remain separate release checklist gates; a cross-build cannot execute ARM code. See CI and the release runbook.